SE How Will The Custom HBM Business Work?
Posted: Thu Aug 20, 2026 7:02 am
Key Takeaways:
In theory, many companies across industries could be interested in customized memory. The memory layers themselves aren’t customized, but the controlling logic can be, which is very useful for chip and system architects. If you’re building a system with standard HBM, all you have to do is acquire the units off the shelf (at present, putting you in line with everyone else who wants some). If you decide that customizing makes sense, then instead of simply buying what you want, you now have a chip-design project to fund and manage. That immediately restricts who can do this. In fact, this capability is largely intended for hyperscalers for three reasons. First, they have the money to do it. Second, AI processing involves a very narrow set of workload types as compared to web servers. You can even dedicate machines to one specific type of workload, which wouldn’t work as well for a web server since you may not know in advance what the workload will be. So the hyperscalers are more likely than most to dedicate a large swath of machines to a specific workload style. Customizing the host and memory makes much more sense in that context. The third motivator reflects the fact that while standards could be set for different workloads, the standardization process takes too long compared with the rapid pace of computing evolution for AI. “JEDEC has been slow in standardization,” said Khurram Malik, associate vice president of data-center memory solutions at Marvell. “Hyperscalers are moving at a much faster pace, and the question becomes, ‘How to customize those HBM base dies based on their workload?’” Customizing gives these companies a way to adapt in concert with computing advancements, rather than waiting for a formal standard. It also may give companies a differentiating edge, depending on what they customize. Beyond hyperscalers, enterprise solutions may join the game. “We started to see more and more that enterprise customers are also trying to build their own XPUs,” noted Malik. “The discussion is still in the early evaluation phase.” A specific example
One company moving forward with a custom HBM implementation is Marvell. It has a division dedicated to custom cloud computing, and it customizes XPUs for clients. Custom XPUs motivate custom memory. “It’s to enable the custom XPUs that we’re developing,” explained Jim Rogers, senior vice president of custom cloud solutions at Marvell. It’s not that hyperscalers all want to do the same thing — it’s rather the opposite. “Different hyperscalers would like to have their own die-to-die interfaces,” said Malik. The fact that the group is generating a custom XPU for each client points to an opportunity to provide a custom HBM stack to match that processor. But to reduce design effort, they have tried to create a single custom version that can work with all the custom XPUs. “We are trying to see what the different customer requirements are and how to navigate through a single HBM offering and address those multiple customers,” said Malik. Wrapping the interface
When customizing a base die, even if one does nothing else custom, the memory controller moves from the host to the base die. Custom versions are generally expected to include optimized interfaces between the host and memory stack. By moving the controller to the base die, one is effectively “wrapping” the standard interface in a custom (or different) one. “If you do cHBM, you need to define how you’re interfacing to the HBM controller, which could be AXI [Arm’s advanced eXtensible interface], or it could be some other methodology,” explained Kruger. “But you need to agree on both sides. It’s about how the data is transported — what format and interface you use.” And there are parametric benefits to doing so. The memory controller is large, and the interface has a huge number of connections. Each of those uses up some of the “beachfront” (the solder balls or connections closest to the outside of the die, which can connect to local chips). In addition, the host will likely be manufactured on one of the latest silicon process nodes, given the investment in a custom design.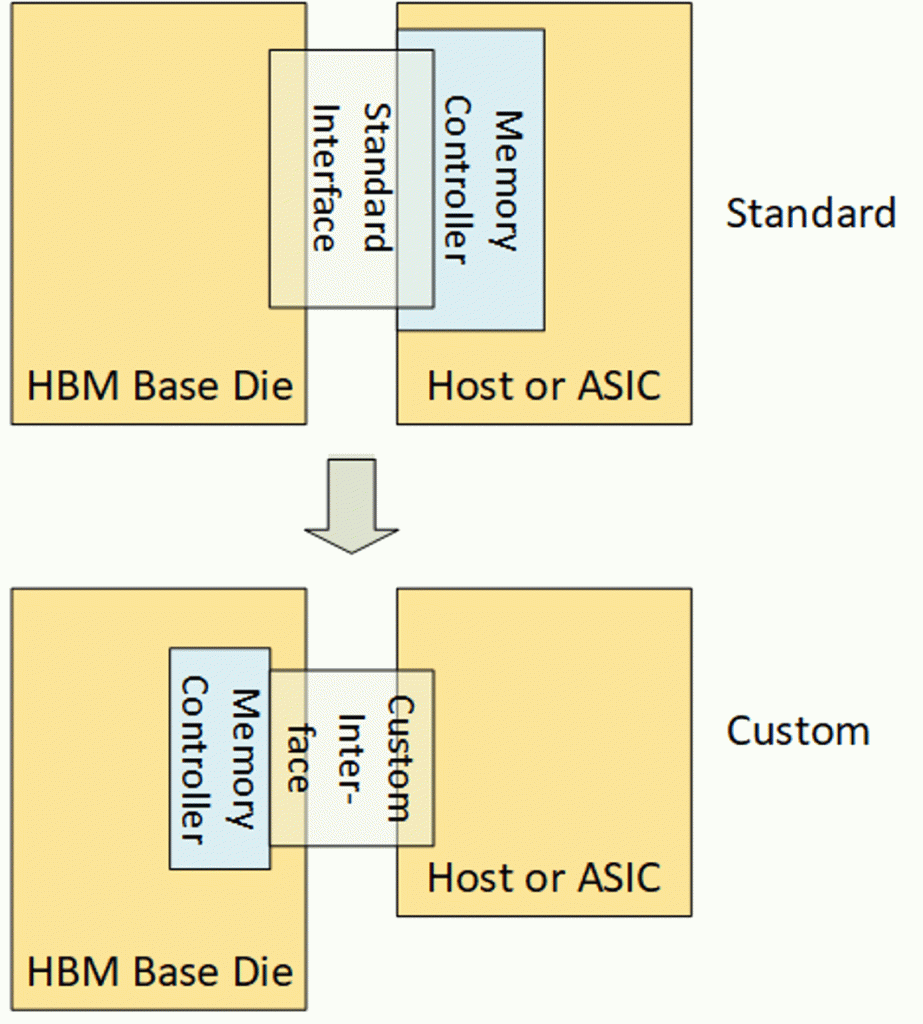 Fig. 1: In custom HBM, the memory controller no longer needs to drive between chips, so it can be much smaller, providing beachfront benefits. Source: Bryon Moyer/Semiconductor Engineering The base die needs a logic process more advanced than a traditional DRAM process, but it doesn’t need to be as expensive as the host process. So the controller adds space to the base die while saving space on the host die. But the area it adds to the base die costs less than the area it saves, making it a net cost win. Another cost saving occurs if the custom interface requires fewer connections than the standard one. The memory PHY area includes all the pads and drivers for external signaling. The controller no longer connects to the host and HBM stack because it’s buried in the base die, but it may still need all the original signals. Yet because they don’t talk to another chip, they don’t require pad space, so they can have less advanced drivers. “You have the memory controller sitting on the logic compute die,” Malik explained. “You put the memory controller onto the custom HBM base die and remove the PHY [since it no longer drives between chips] because the PHY is the biggest block sitting on the compute die, and that PHY is just for connectivity. So remove the PHY and put on UCIe or another die-to-die interface. That is around 70% smaller than a standard DRAM PHY. It enables 25% more compute capabilities on the compute die. It reduces the overall power, and it increases the efficiency of the whole XPU die.” A key benefit comes from the ability to connect to more HBM stacks. “It depends upon the die size of the XPU, but now you have more shoreline, so you can connect more HBMs to provide more memory capacity for those compute tiles,” said Malik. The memory-maker’s role in this effort is to provide a “TSV PHY,” which is IP that acts as a TSV template for the base die. Consider HBM5, for instance. “You’d have 2,048 bits connecting to this thing called the TSV5,” said Kruger. “That’s IP from the memory maker that connects to their stack of dies, and also directs how to interface with those connections and do tests.” Of course, customization can go beyond just the interface. Companies may also want to tweak other features. “There are standards for RAS [reliability, availability, serviceability], but then people have their own thoughts on what’s needed and how they want to do that as well. So that’s an area where things get customized,” said Kruger. “You’ll have a control and management unit that will have this RAS telemetry aggregation and collection. How you send it to the rest of the system needs to be defined to understand how it fits in the larger system.” Who designs these things?
While customization could be limited to the controller move, that’s unlikely, because it’s simpler to make other beneficial changes when the device is open. But there’s no set way to do this, and each project is likely a negotiation. The four basic steps to consider are design, manufacturing (and wafer test), assembly, and final test. Of the four, design is the hardest piece because the others become more of a matter of capacity. Design requires a team, tools, and a vision of how more memory can impact performance and power. In the past, that might have limited the companies capable of doing this to the memory makers or fabless companies, but today, the hyperscalers have deep expertise in semiconductor design. In that order, the first option seems unlikely. Memory makers are plenty busy with what’s on their plates, and taking on custom design may not fit well. We can’t speak for all the memory folks (and most didn’t want to talk on the record), but at least one company is concerned about being expected to do custom base die designs. “Now, everything the customer wants is custom because they want higher bandwidth, ” said Jaesik Lee, vice president of package engineering at SK hynix America, in a presentation. “But memory companies need to do the design and manufacturing [of custom HBM], and we are resource-constrained.” Synopsys’s Kruger seconded the resource issue, noting that it’s a big lift to do one of these projects. “These people don’t have teams waiting around to do all these custom designs,” he said. “You need to have a significant volume to justify a custom development like this, so it’s going to limit the number just based on that.” If the memory guys are out, that leaves fabless folks and the hyperscalers. It’s not clear how many fabless companies will be involved in this, but given Marvell’s project, it’s reasonable to expect others will do this, as well. Still, each such project is custom. “It is really essential to work with the end hyperscaler customers,” said Malik. “Even though you can stitch blocks together, tuning and optimizations are still required. And every hyperscaler is different.” Who builds the stack?
For standard HBM4, the memory maker gets the tested logic die from the logic foundry, assembles the stack, tests the finished product, and ships it. For a custom version, the memory maker still builds the memory dies for the stack, but it no longer owns the base-die design. Do they still take the custom base die and build the stack? Do they have the capacity to do that in a market like the one we have now? It turns out there’s no single answer on who will perform stack integration. Each project will spin up by forming an agreement between a memory house, a logic foundry, and perhaps an assembly facility that can handle stack bonding (expected to be hybrid bonding for HBM4E and after, at least for 16-high stacks). Who owns that flow can vary by project. “There are different business engagement models with different customers,” said Malik. “Some customers give full ownership of the logic to the guys designing it while taking full ownership of the integration. Some give the logic guys certain responsibilities and memory guys other responsibilities. And in some cases, some customers like to take full ownership themselves by working with a logic partner as well as with memory partners.” In recent news, TSMC announced it was working with Winbond. Winbond will provide memory wafers while TSMC assembles the stack. The headline there was that this took pressure off the other three main memory makers. A poor-person’s HBM?
Given memory shortages, designers have to be more creative about how to get enough memory — especially for companies that may not be near the top of the list of who gets memory allocation. An alternative stacks standard DRAM dies atop a host. These assemblies aren’t as tall as a true HBM stack, but they may integrate as many as four DRAM dies atop one another. Even though HBM hasn’t moved to hybrid bonding yet, other DRAM dies have. “In designs that have already taped out, the bottom logic die is flipped face up and hybrid bonds connect to the downward-facing DRAM wafer on top,” explained Kruger. “That DRAM wafer has a
Source: https://semiengineering.com/how-will-th ... ness-work/
- HBM4 allows a customized base die, a capability that primarily targets hyperscalers.
- Exactly how these projects proceed will vary by project, but the scarce resource is design teams and tools.
- Although memory supply is tight now, cHBM isn’t expected to further burden demand.
In theory, many companies across industries could be interested in customized memory. The memory layers themselves aren’t customized, but the controlling logic can be, which is very useful for chip and system architects. If you’re building a system with standard HBM, all you have to do is acquire the units off the shelf (at present, putting you in line with everyone else who wants some). If you decide that customizing makes sense, then instead of simply buying what you want, you now have a chip-design project to fund and manage. That immediately restricts who can do this. In fact, this capability is largely intended for hyperscalers for three reasons. First, they have the money to do it. Second, AI processing involves a very narrow set of workload types as compared to web servers. You can even dedicate machines to one specific type of workload, which wouldn’t work as well for a web server since you may not know in advance what the workload will be. So the hyperscalers are more likely than most to dedicate a large swath of machines to a specific workload style. Customizing the host and memory makes much more sense in that context. The third motivator reflects the fact that while standards could be set for different workloads, the standardization process takes too long compared with the rapid pace of computing evolution for AI. “JEDEC has been slow in standardization,” said Khurram Malik, associate vice president of data-center memory solutions at Marvell. “Hyperscalers are moving at a much faster pace, and the question becomes, ‘How to customize those HBM base dies based on their workload?’” Customizing gives these companies a way to adapt in concert with computing advancements, rather than waiting for a formal standard. It also may give companies a differentiating edge, depending on what they customize. Beyond hyperscalers, enterprise solutions may join the game. “We started to see more and more that enterprise customers are also trying to build their own XPUs,” noted Malik. “The discussion is still in the early evaluation phase.” A specific example
One company moving forward with a custom HBM implementation is Marvell. It has a division dedicated to custom cloud computing, and it customizes XPUs for clients. Custom XPUs motivate custom memory. “It’s to enable the custom XPUs that we’re developing,” explained Jim Rogers, senior vice president of custom cloud solutions at Marvell. It’s not that hyperscalers all want to do the same thing — it’s rather the opposite. “Different hyperscalers would like to have their own die-to-die interfaces,” said Malik. The fact that the group is generating a custom XPU for each client points to an opportunity to provide a custom HBM stack to match that processor. But to reduce design effort, they have tried to create a single custom version that can work with all the custom XPUs. “We are trying to see what the different customer requirements are and how to navigate through a single HBM offering and address those multiple customers,” said Malik. Wrapping the interface
When customizing a base die, even if one does nothing else custom, the memory controller moves from the host to the base die. Custom versions are generally expected to include optimized interfaces between the host and memory stack. By moving the controller to the base die, one is effectively “wrapping” the standard interface in a custom (or different) one. “If you do cHBM, you need to define how you’re interfacing to the HBM controller, which could be AXI [Arm’s advanced eXtensible interface], or it could be some other methodology,” explained Kruger. “But you need to agree on both sides. It’s about how the data is transported — what format and interface you use.” And there are parametric benefits to doing so. The memory controller is large, and the interface has a huge number of connections. Each of those uses up some of the “beachfront” (the solder balls or connections closest to the outside of the die, which can connect to local chips). In addition, the host will likely be manufactured on one of the latest silicon process nodes, given the investment in a custom design.
Fig. 1: In custom HBM, the memory controller no longer needs to drive between chips, so it can be much smaller, providing beachfront benefits. Source: Bryon Moyer/Semiconductor Engineering The base die needs a logic process more advanced than a traditional DRAM process, but it doesn’t need to be as expensive as the host process. So the controller adds space to the base die while saving space on the host die. But the area it adds to the base die costs less than the area it saves, making it a net cost win. Another cost saving occurs if the custom interface requires fewer connections than the standard one. The memory PHY area includes all the pads and drivers for external signaling. The controller no longer connects to the host and HBM stack because it’s buried in the base die, but it may still need all the original signals. Yet because they don’t talk to another chip, they don’t require pad space, so they can have less advanced drivers. “You have the memory controller sitting on the logic compute die,” Malik explained. “You put the memory controller onto the custom HBM base die and remove the PHY [since it no longer drives between chips] because the PHY is the biggest block sitting on the compute die, and that PHY is just for connectivity. So remove the PHY and put on UCIe or another die-to-die interface. That is around 70% smaller than a standard DRAM PHY. It enables 25% more compute capabilities on the compute die. It reduces the overall power, and it increases the efficiency of the whole XPU die.” A key benefit comes from the ability to connect to more HBM stacks. “It depends upon the die size of the XPU, but now you have more shoreline, so you can connect more HBMs to provide more memory capacity for those compute tiles,” said Malik. The memory-maker’s role in this effort is to provide a “TSV PHY,” which is IP that acts as a TSV template for the base die. Consider HBM5, for instance. “You’d have 2,048 bits connecting to this thing called the TSV5,” said Kruger. “That’s IP from the memory maker that connects to their stack of dies, and also directs how to interface with those connections and do tests.” Of course, customization can go beyond just the interface. Companies may also want to tweak other features. “There are standards for RAS [reliability, availability, serviceability], but then people have their own thoughts on what’s needed and how they want to do that as well. So that’s an area where things get customized,” said Kruger. “You’ll have a control and management unit that will have this RAS telemetry aggregation and collection. How you send it to the rest of the system needs to be defined to understand how it fits in the larger system.” Who designs these things?While customization could be limited to the controller move, that’s unlikely, because it’s simpler to make other beneficial changes when the device is open. But there’s no set way to do this, and each project is likely a negotiation. The four basic steps to consider are design, manufacturing (and wafer test), assembly, and final test. Of the four, design is the hardest piece because the others become more of a matter of capacity. Design requires a team, tools, and a vision of how more memory can impact performance and power. In the past, that might have limited the companies capable of doing this to the memory makers or fabless companies, but today, the hyperscalers have deep expertise in semiconductor design. In that order, the first option seems unlikely. Memory makers are plenty busy with what’s on their plates, and taking on custom design may not fit well. We can’t speak for all the memory folks (and most didn’t want to talk on the record), but at least one company is concerned about being expected to do custom base die designs. “Now, everything the customer wants is custom because they want higher bandwidth, ” said Jaesik Lee, vice president of package engineering at SK hynix America, in a presentation. “But memory companies need to do the design and manufacturing [of custom HBM], and we are resource-constrained.” Synopsys’s Kruger seconded the resource issue, noting that it’s a big lift to do one of these projects. “These people don’t have teams waiting around to do all these custom designs,” he said. “You need to have a significant volume to justify a custom development like this, so it’s going to limit the number just based on that.” If the memory guys are out, that leaves fabless folks and the hyperscalers. It’s not clear how many fabless companies will be involved in this, but given Marvell’s project, it’s reasonable to expect others will do this, as well. Still, each such project is custom. “It is really essential to work with the end hyperscaler customers,” said Malik. “Even though you can stitch blocks together, tuning and optimizations are still required. And every hyperscaler is different.” Who builds the stack?
For standard HBM4, the memory maker gets the tested logic die from the logic foundry, assembles the stack, tests the finished product, and ships it. For a custom version, the memory maker still builds the memory dies for the stack, but it no longer owns the base-die design. Do they still take the custom base die and build the stack? Do they have the capacity to do that in a market like the one we have now? It turns out there’s no single answer on who will perform stack integration. Each project will spin up by forming an agreement between a memory house, a logic foundry, and perhaps an assembly facility that can handle stack bonding (expected to be hybrid bonding for HBM4E and after, at least for 16-high stacks). Who owns that flow can vary by project. “There are different business engagement models with different customers,” said Malik. “Some customers give full ownership of the logic to the guys designing it while taking full ownership of the integration. Some give the logic guys certain responsibilities and memory guys other responsibilities. And in some cases, some customers like to take full ownership themselves by working with a logic partner as well as with memory partners.” In recent news, TSMC announced it was working with Winbond. Winbond will provide memory wafers while TSMC assembles the stack. The headline there was that this took pressure off the other three main memory makers. A poor-person’s HBM?
Given memory shortages, designers have to be more creative about how to get enough memory — especially for companies that may not be near the top of the list of who gets memory allocation. An alternative stacks standard DRAM dies atop a host. These assemblies aren’t as tall as a true HBM stack, but they may integrate as many as four DRAM dies atop one another. Even though HBM hasn’t moved to hybrid bonding yet, other DRAM dies have. “In designs that have already taped out, the bottom logic die is flipped face up and hybrid bonds connect to the downward-facing DRAM wafer on top,” explained Kruger. “That DRAM wafer has a
Source: https://semiengineering.com/how-will-th ... ness-work/